· Timothy O'Brien
What’s a Looped Transformer? More Reasoning, Less to Read.
Reusing a model’s layers can improve reasoning without producing more written steps for a monitor to inspect.
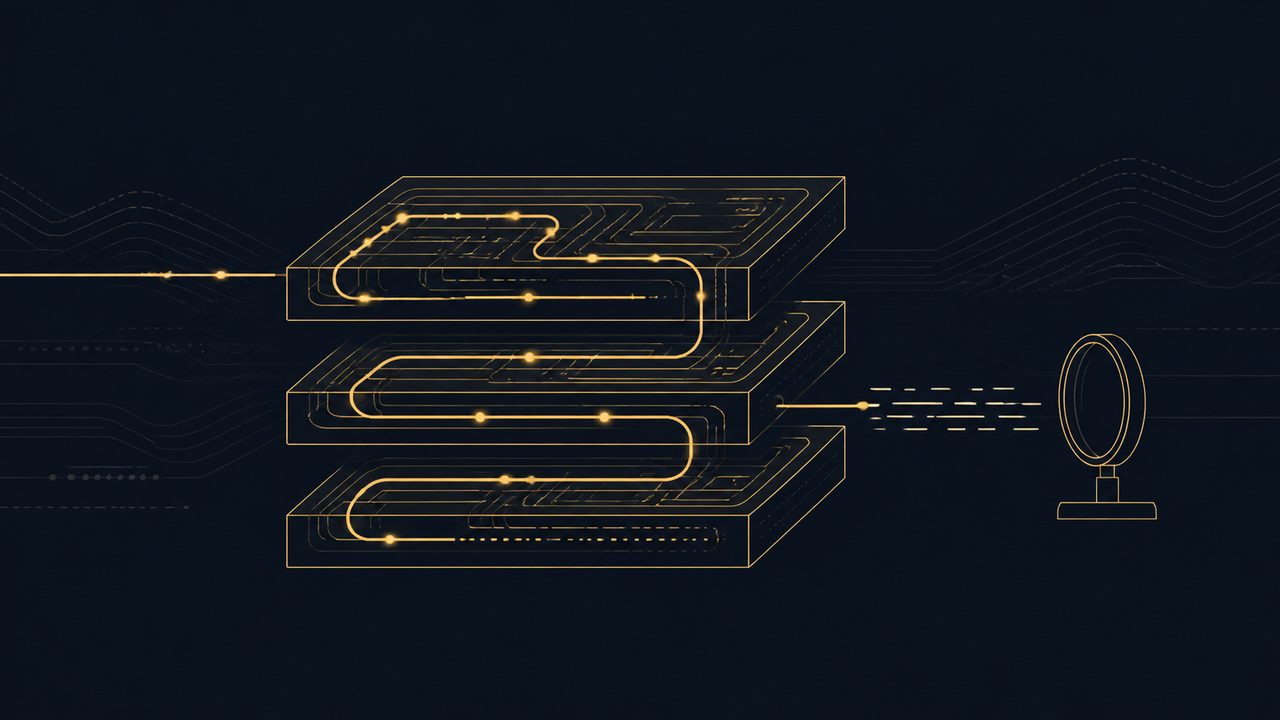
A looped transformer reuses some of its neural-network layers to do more computation before producing the next token. That can improve reasoning without requiring a larger set of model weights. A study on LessWrong suggests it can also disproportionately improve reasoning that happens without a written chain of thought, raising questions about how much oversight a reasoning transcript can provide.[1][2]
The model runs through the same layers again
A conventional transformer processes text through a sequence of layers. Those layers update an internal numerical representation of the text, eventually producing probabilities for the next token. Each layer has its own learned parameters, or weights.
A looped transformer sends that internal representation through a shared group of layers repeatedly. The weights stay the same; the representation changes with each pass. Think of applying the same editing procedure to successive drafts rather than hiring another editor for every revision.
This isn’t an agent loop that calls a model, runs a tool, and feeds the result back. The repetition happens inside the neural network, before it selects the next token.
NVIDIA’s Dory is a concrete example: a four-billion-parameter model that repeatedly applies a shared block of layers. Its loop count can be changed at inference time. NVIDIA recommends starting with two loops, with additional loops available when accuracy matters more than computation per token.[2]
The attraction is straightforward. Reusing weights lets a relatively small model perform more processing without storing a different set of weights for every pass. But the extra processing costs compute, and cache memory depends on the implementation. NVIDIA explicitly recommends measuring end-to-end latency and cost because additional loops can also reduce the number of tokens generated.[2]
Extra computation doesn’t have to become extra words
Chain of thought is the step-by-step text a model generates while working toward an answer. Those intermediate tokens can support further computation, and a monitoring system can inspect them for concerning behavior.
Looping adds computation inside the model’s numerical representations. The intermediate passes don’t have to be translated into words. A looped model can still produce a chain of thought; it simply has another place to perform useful work.
That distinction matters when safety systems depend on reading the reasoning. A transcript can contain useful evidence without recording every computation that produced the answer.
A model that needs fewer written steps can leave its monitor with less evidence to inspect.
Read the study: what improved when they added loops?
Alek Westover and Nick Kuhn published their experiments on NVIDIA’s publicly available Dory model in “Looping a transformer increases no-CoT capabilities more than general capabilities”. This is an experimental write-up on LessWrong, separate from NVIDIA’s model-release documentation.[1]
They compared performance across loop counts using a No-CoT Reasoning Index, or NCRI; a broader benchmark aggregate they call mini-ECI; and text-prediction quality.[1]
From one to eight loops, NCRI rose by about 18 points with their best prompt format, versus about 13 with a plain prompt. Meanwhile, mini-ECI changed by at most about 1.5 points. These are different scales: the important comparison is against the relationship observed across other models. That relationship predicted only about two NCRI points from the broader capability improvement.[1]
Text-prediction quality barely changed beyond the second loop. Additional loops were therefore helping these no-CoT tasks much more than the other measurements suggested.[1]
There’s an important qualification: even at eight loops, Dory remained below the cross-model NCRI-versus-mini-ECI trend. The finding is about the disproportionate improvement within Dory, not proof that looped models universally have unusually high hidden-reasoning capability.[1]
They also trained a modified model to evade a monitor
The researchers separately tested a cache-sharing configuration that carries the final loop’s internal attention state into subsequent token processing. That creates a deeper recurrent computation pathway than ordinary looping alone.[1]
They trained this recurrent Dory on structured math tasks, then rewarded correct solutions while penalizing reasoning that a monitor could identify. The recurrent model learned to solve problems while replacing almost all its written reasoning with meaningless filler tokens such as “ well.” On the simpler tasks, the concealment also worked against a stronger, held-out monitor.[1]
This was deliberately incentivized concealment in a controlled experiment, not evidence of spontaneous malicious intent. The training comparisons used one seed per arm; some broader-task runs were unstable and involved checkpoint selection. Those limitations matter.[1]
Test the oversight alongside the capability
The study concerns one small model and a limited collection of tasks. It lacks an otherwise identically trained, non-looped baseline. Its chain-of-thought controllability tests were also inconclusive because Dory performed near the floor at every tested loop count.[1]
Even so, it identifies a concrete evaluation requirement. When developers increase loop counts or change cache-sharing behavior, they should measure both task performance and whether their monitors still detect the behavior they’re supposed to catch.
For anyone building an agent, a readable reasoning trace should remain one source of evidence alongside tool logs, permission boundaries, and independently checked results. More capable internal computation is a reason to retest that oversight, not assume the old monitoring results still apply.
Sources
Newsletter
Get the notes by email
New essays and chapter updates, a few times a month. No spam — unsubscribe any time.